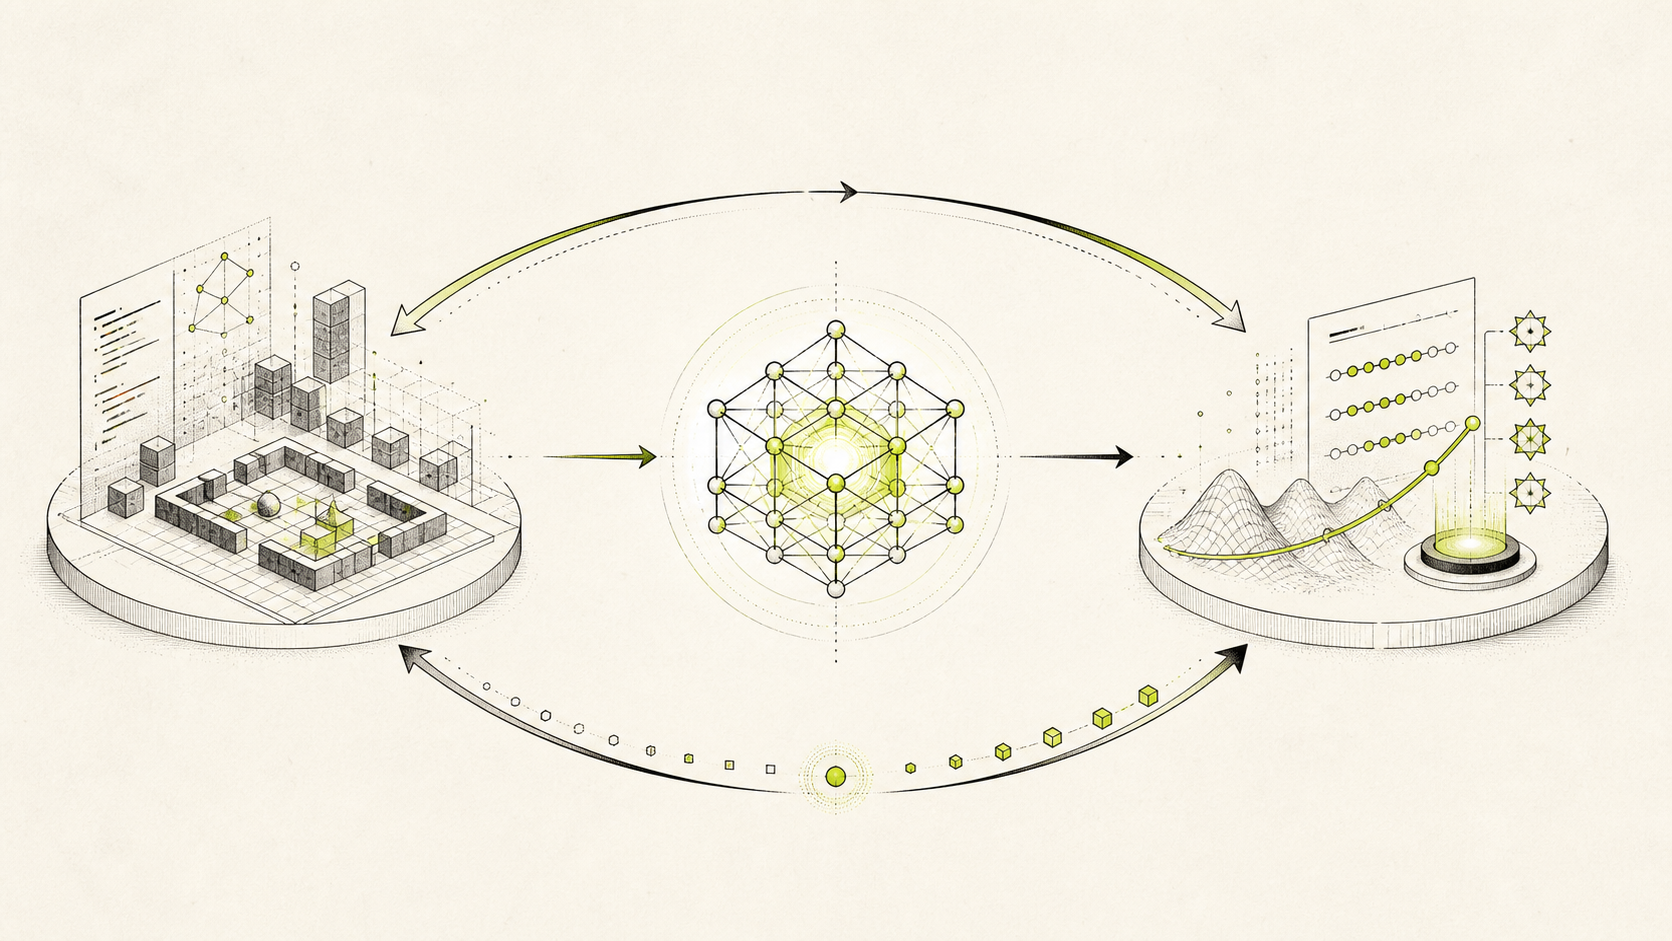
Verimium builds reinforcement-learning environments that push the frontier of AI model capabilities. We turn consequential engineering work into scored, repeatable worlds where models can practice, fail, recover, and improve against objective outcomes. SeniorMLE-bench is one expression of that platform: production-shaped ML tasks that reveal whether a model can do the kind of work senior engineers actually ship.
Team
Mohammad Moghimi
Mohammad was a tech lead at Google DeepMind and Google Research, where he led evaluations for Gemini Health and worked on retrieval for large language models. Most of that work is the question this benchmark asks: what a model measurably does on real work, rather than what a demo suggests it can do. He holds a PhD in machine learning from Cornell University.
Ehsan Saberian
Ehsan built recommendation and ranking systems at scale at Roblox and Netflix, where personalization is judged by what it changes in production rather than by an offline number. That is the shape of the tasks in SeniorMLE-bench: long-horizon ML engineering with a verifier at the end. He holds a PhD in machine learning from UC San Diego.
Join us
We are hiring machine-learning engineers to build and calibrate tasks: people who have shipped models into production and can tell a benchmark that measures real work from one that measures a demo.
Send us an email. Tell us what you have shipped and what it changed — a link to the work is worth more than a cover letter.